AI Mentions
Ahrefs Free AI Visibility Checker: What You Get, Limitations & Alternatives
Yes, Ahrefs has a free AI Visibility Checker. You can enter a brand name, inspect its presence across six AI search experiences, and see…
Imagine spending an afternoon preparing an llms.txt file for your website.
You select your most important pages, write clear descriptions, organize everything into Markdown, and upload the finished file. An SEO tool confirms that it’s accessible and marks your website as more AI-ready.
A week later, you check ChatGPT, Google AI Mode, and Perplexity.
Nothing obvious has changed.
Your competitors still appear in answers where your website doesn’t. Your citation tracking dashboard shows roughly the same results, and there is no clear evidence that an AI system has even requested the new file.
Was the implementation a waste of time?
Not necessarily. But it’s worth asking whether the file was ever likely to solve the problem you were trying to fix.
The idea behind llms.txt is reasonable: provide AI systems with a clean, concise guide to a website’s important content rather than making them navigate every HTML page independently.
The difficulty is distinguishing a sensible technical convention from a proven search visibility strategy.
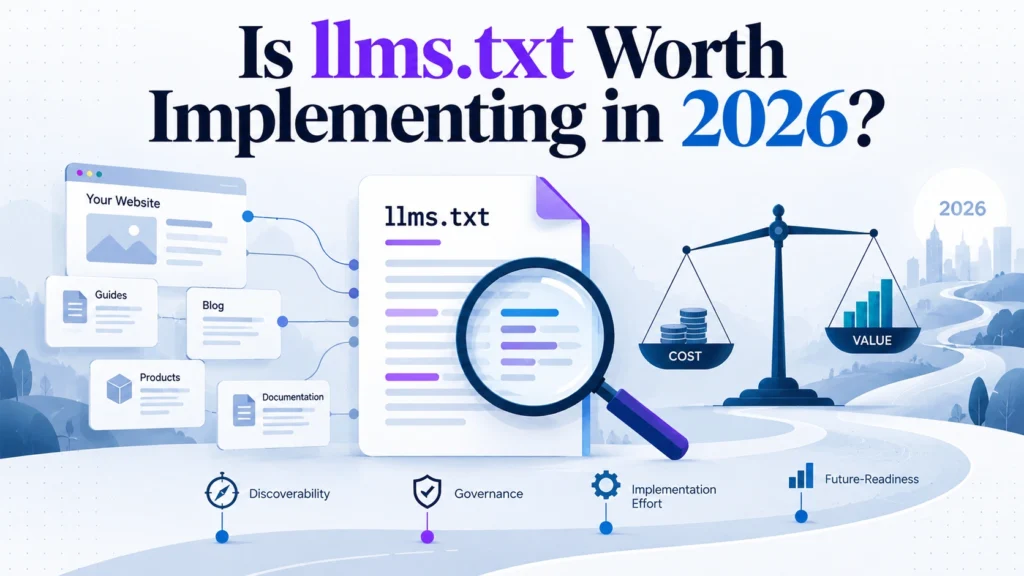
As of October 2026, there is a credible use case for llms.txt as an agent-facing content guide. There is not sufficient public evidence to treat it as a reliable way to increase rankings, brand mentions, or citations across major AI search platforms.
That distinction matters because Generative Engine Optimization (GEO) is becoming an established part of digital marketing, and companies are increasingly being sold technical solutions before their effectiveness has been established.
In this guide, we’ll examine what llms.txt actually does, what major AI providers have confirmed, where the evidence remains incomplete, and how to decide whether implementing it deserves a place on your technical SEO roadmap.
For the wider context, our complete guide to GEO tools explains how AI visibility monitoring, technical accessibility, and content optimization fit together.
llms.txt is a proposed website convention that provides AI agents and language-model-based systems with a concise overview of a website’s important content.
The proposal was introduced by Jeremy Howard on September 3, 2024, and its second version was published on August 10, 2026.
The underlying idea is straightforward.
Websites are built primarily for human visitors. Pages contain navigation menus, advertising, JavaScript, interface elements, and other material that may not be essential to an AI system trying to answer a specific question.
An agent searching for a software application’s API documentation, for example, may need only the authentication reference and a relevant implementation guide.
The llms.txt proposal suggests providing a structured entry point that tells an agent where that information is located.
Instead of acting as a comprehensive index of every URL, the file offers a curated list of useful resources, ideally accompanied by clean Markdown versions of the underlying pages.
The official proposal is available at llmstxt.org.
A website publishes a Markdown file at /llms.txt, or at a more specific path such as /docs/llms.txt.
The file typically includes:
An AI agent that supports the convention can retrieve the file, identify relevant resources, and follow the corresponding links.
But there is an important condition: the agent must actually discover and choose to use the file.
Publishing llms.txt doesn’t automatically change how every language model retrieves information. Nor does it force an AI search platform to prioritize the pages listed inside it.
The file provides information to systems that decide to consume it. It doesn’t control whether they do.
Version two introduced more explicit mechanisms for discovering llms.txt and related Markdown resources.
Alongside the conventional file location, the updated proposal recommends using link relations that identify a Markdown version of a page and the llms.txt file describing it.
For example, rel="alternate" with type="text/markdown" can point to a Markdown representation, while rel="describedby" can identify the relevant llms.txt resource.
These relationships can appear in HTML or HTTP response headers.
This makes the proposal more useful for workflows where agents retrieve documentation or structured reference material.
However, the improvement is to the proposed convention itself. It doesn’t establish that every major AI search engine has adopted it.
Not in the same sense as established web protocols.
llms.txt remains a community proposal, not a formally ratified IETF, W3C, or ISO standard.
That doesn’t make it useless. Many useful web conventions begin as practical solutions before acquiring broader support.
But it does mean that implementations can differ, and support should not be assumed merely because a website or software tool recognizes the filename.
The distinction becomes clearer when comparing llms.txt with other familiar website files.
| File | Primary Purpose | What It Does Not Guarantee |
|---|---|---|
robots.txt |
Communicates crawler access preferences and restrictions | Search rankings or universal compliance by all automated clients |
sitemap.xml |
Lists URLs for supported search-engine discovery | Indexing or ranking |
llms.txt |
Provides a curated guide to website content for compatible agents | Automatic ingestion, AI citations, or better rankings |
llms-full.txt |
Provides an optional expanded body of content for compatible workflows | That an AI system will download or use the full document |
The filename llms.txt may resemble robots.txt, but the two serve fundamentally different purposes.
A robots file communicates access rules to compliant crawlers. An llms.txt file describes content and suggests where an agent should look.
It is not a permissions system, a privacy control, or a substitute for the site’s existing technical SEO infrastructure.
Google’s position is unusually clear.
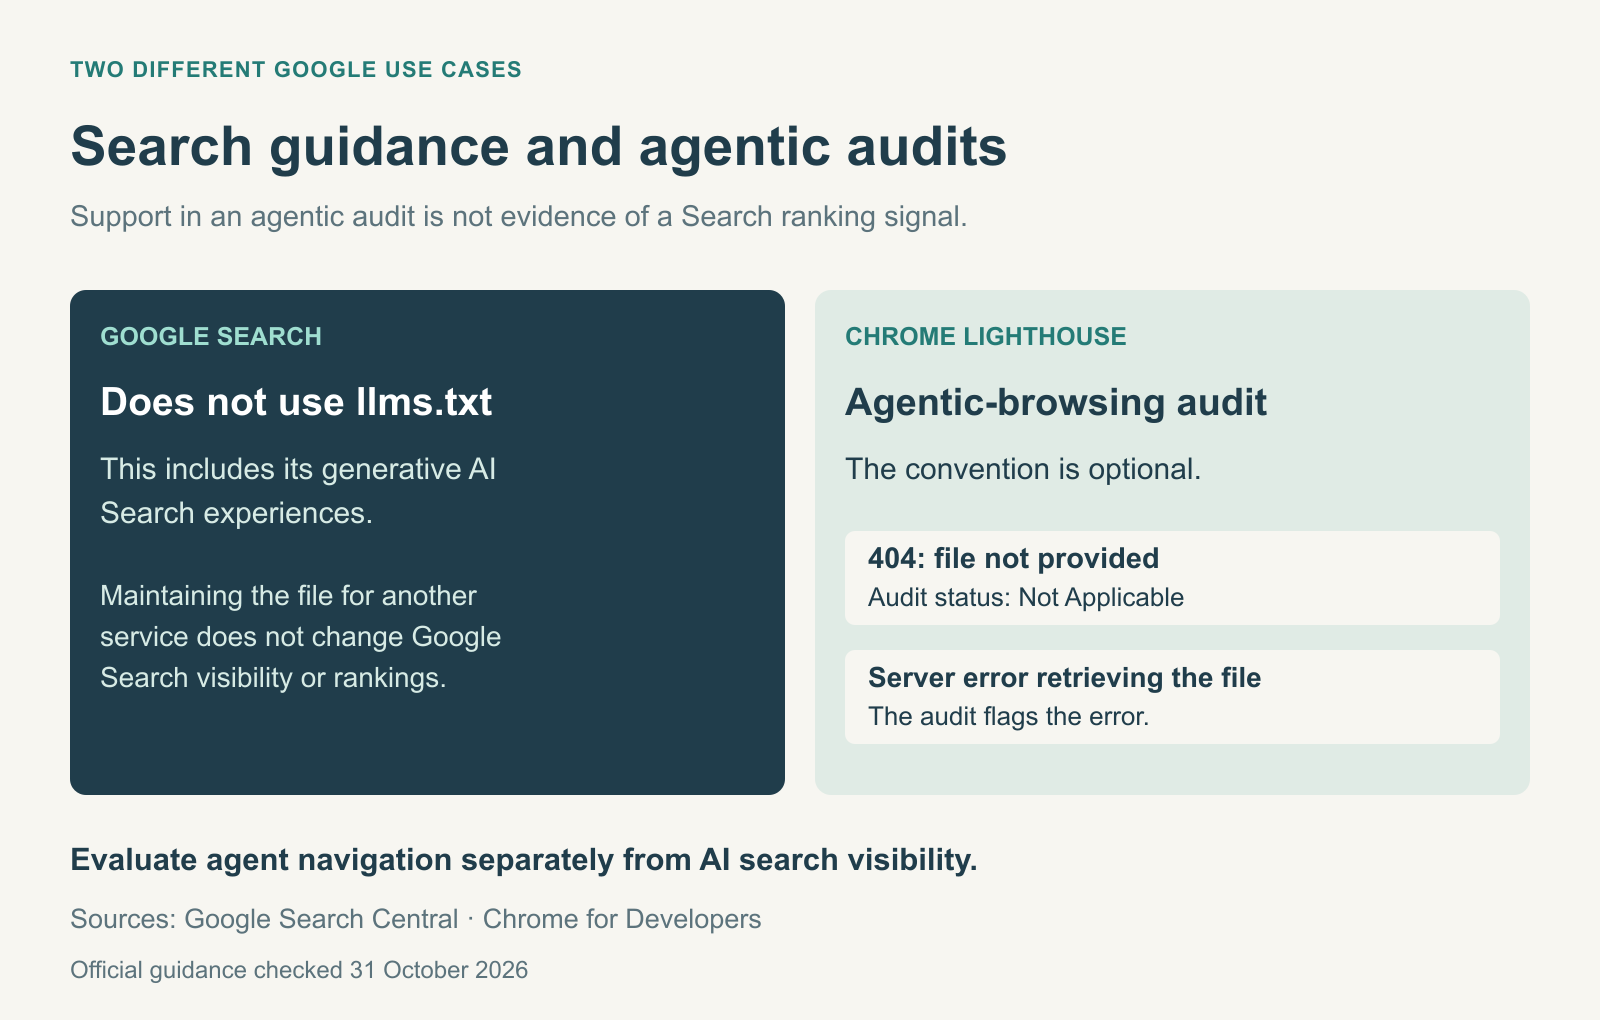
In its official guidance on optimizing websites for generative AI features, Google states that Google Search doesn’t use llms.txt files, including for generative AI Search experiences.
On June 15, 2026, Google clarified that website owners can publish and maintain the files for other services without either helping or harming their visibility or rankings in Google Search.
That guidance applies to Google’s Search systems, including their generative AI features.
Source: Google Search Central — Optimizing for Generative AI.
This creates a straightforward decision.
If your only objective is to increase visibility in Google’s AI Overviews or AI Mode, creating llms.txt should not be treated as an optimization supported by Google’s own documentation.
The fact that Google can crawl or index different types of text files doesn’t mean it treats every file as a special ranking or retrieval signal.
Here’s where the discussion becomes more interesting.
Chrome’s Lighthouse documentation includes an llms.txt check within its agentic browsing audits.
That might appear to contradict Google’s Search guidance.
It doesn’t.
Lighthouse describes the file as an emerging convention that may help agents understand a website’s structure.
Importantly, the audit treats a missing file that returns HTTP 404 as Not Applicable, rather than a failure. It flags server errors when trying to retrieve the file.
In other words, Lighthouse acknowledges the convention without requiring every website to implement it.
Source: Chrome Lighthouse — llms.txt.
The distinction is between two different use cases:
Evidence of the second is not proof of improved performance in the first.
A website shouldn’t interpret a successful Lighthouse check as confirmation that Google AI Mode will recommend it more frequently.
This question is more difficult to answer than the Google question because public documentation doesn’t establish universal automatic support.
Several major AI companies publish llms.txt files for their own developer documentation.
That is meaningful adoption of the publishing convention.
But publishing a file and making an AI search product consume that file are different things.
OpenAI publishes information about the crawlers and user agents associated with its products.
Its official crawler documentation distinguishes among:
| OpenAI User Agent | Documented Purpose |
|---|---|
OAI-SearchBot |
Crawling associated with ChatGPT Search |
GPTBot |
Crawling content potentially used for model training |
ChatGPT-User |
Fetching content in certain user-initiated interactions |
OpenAI recommends allowing OAI-SearchBot when a website wants to be eligible for ChatGPT Search discovery.
The same documentation explains that the search and training controls are separate.
However, it doesn’t establish that ChatGPT Search automatically retrieves every site’s llms.txt file or treats that file as a ranking signal.
OpenAI itself publishing an llms.txt resource for developer documentation is evidence that the format can serve documentation workflows. It isn’t proof of a general ChatGPT Search optimization benefit.
Source: OpenAI — Overview of Crawlers.
Anthropic also publishes guidance on managing its different web crawlers through robots.txt.
Its published crawler categories distinguish model-development crawling, search-related retrieval, and user-initiated requests.
These are meaningful controls for website owners.
But Anthropic providing an llms.txt file for developer documentation doesn’t establish that Claude automatically consults every website’s file before generating answers.
It is plausible that particular agent workflows or integrations may use the convention.
The evidence should be evaluated at that product or workflow level rather than generalized across the entire Claude ecosystem.
Source: Anthropic — Web Crawlers and Site Owner Controls.
The same caution applies to Perplexity and other AI search products.
Public adoption of the file format, third-party tools that generate it, or occasional requests visible in server logs are not enough to establish systematic use in answer generation.
A system could fetch the file and ignore its contents. It could use the information for navigation without displaying the source as a citation. Another could rely entirely on its search index and never request the file.
Without a documented retrieval policy or reproducible test, assigning a ranking or citation benefit to those behaviors would be speculative.
A useful way to evaluate the proposal is to separate evidence of adoption from evidence of effectiveness.
They are not interchangeable.
| Evidence | What It Establishes | What It Doesn’t Establish |
|---|---|---|
A website publishes llms.txt |
The publisher supports the convention | AI systems use it |
| A documentation platform generates it automatically | The format has implementation support | It improves AI search visibility |
| An agent successfully reads the file | The file can serve that agent’s workflow | Every AI assistant reads it |
Server logs show requests for /llms.txt |
A client requested the resource | The file influenced a generated answer |
| AI citations increase after implementation | An observable change occurred | The file caused the increase |
| A controlled agent completes a task more reliably with the file | Evidence of utility for that tested workflow | A universal benefit across AI platforms |
The strongest currently documented use case is helping compatible agents navigate complex documentation and reference material.
The weakest claim is that publishing an llms.txt file automatically makes a business more likely to appear in ChatGPT recommendations or Google’s AI-generated answers.
Those are fundamentally different outcomes.
A growing number of websites publishing a convention is evidence of interest.
It isn’t necessarily evidence that the convention produces its advertised benefit.
For example, a content management system might introduce automatic llms.txt generation. Thousands of websites could then publish files without their owners making a deliberate optimization decision.
That would increase the number of available files even if no major AI search product changed its retrieval behavior.
Likewise, a generator reporting that your website is now AI-ready may be assessing whether the file exists and follows an expected format.
That’s a technical implementation check, not a measured improvement in AI visibility.
There are situations where the proposal makes practical sense, even without a demonstrated search-ranking benefit.
This is arguably the strongest use case.
A software documentation website may contain hundreds of pages describing authentication, endpoints, error handling, configuration, and examples.
An agent helping a developer solve a technical problem doesn’t necessarily need the entire documentation library.
A curated llms.txt file can identify the relevant sections and point the agent toward clean Markdown resources.
If the agent is explicitly configured to use the file, teams can test whether it finds correct information more quickly or completes developer tasks more reliably.
That is a concrete operational benefit, separate from search rankings.
Consider a university, government service, or large organization publishing many policies and reference documents.
A maintained file could help compatible agents locate current policies, organizational information, and important reference pages.
However, it also creates a maintenance obligation.
If a policy changes and the llms.txt file continues pointing to outdated information, the curated guide could become an additional source of confusion.
The usefulness of the implementation depends on the quality and currency of its contents.
A company developing its own support assistant, research agent, or documentation tool can explicitly instruct that system to consult its llms.txt file.
In that situation, the organization controls the consumer.
It can measure whether the file improves navigation, reduces unnecessary fetching, or produces more reliable answers to documented tasks.
That is substantially easier to evaluate than trying to influence an external AI search product whose retrieval rules aren’t fully disclosed.
For a typical service business with a homepage, service pages, contact information, and a few dozen articles, the potential benefit is less obvious.
If existing HTML pages are accessible, well-organized, and clearly written, there may be little additional navigation complexity for an llms.txt file to resolve.
The file can still be created at relatively low cost.
But low cost is not the same as proven value, especially when the website has unresolved technical issues or outdated business information.
The most important question isn’t whether the file can be created. It’s what other work the team would delay to create and maintain it.
I’d give llms.txt a low priority when:
These issues have more direct and established implications for website accessibility, SEO, or content usefulness.
For diagnosing those problems, our comparison of SEO audit tools explains how technical crawlers identify site architecture, internal linking, and accessibility issues.
The practical priority should be to make the underlying website reliable before creating an alternative guide to that website.
An llms.txt file can’t compensate for content that is inaccurate, inaccessible, or missing altogether.
If you’ve identified a genuine use case, implementation can be straightforward.
The challenge is less about writing Markdown and more about choosing which resources deserve attention.
Start with pages that answer meaningful questions about the website, organization, or product.
For a software company, those might include product documentation, setup instructions, API references, pricing information, and troubleshooting resources.
For an editorial publication, they might include its main topic guides, methodology, and pages containing original research.
Don’t automatically include every URL in the XML sitemap.
The proposal is intended to provide a concise, curated view, not reproduce the entire site’s navigation.
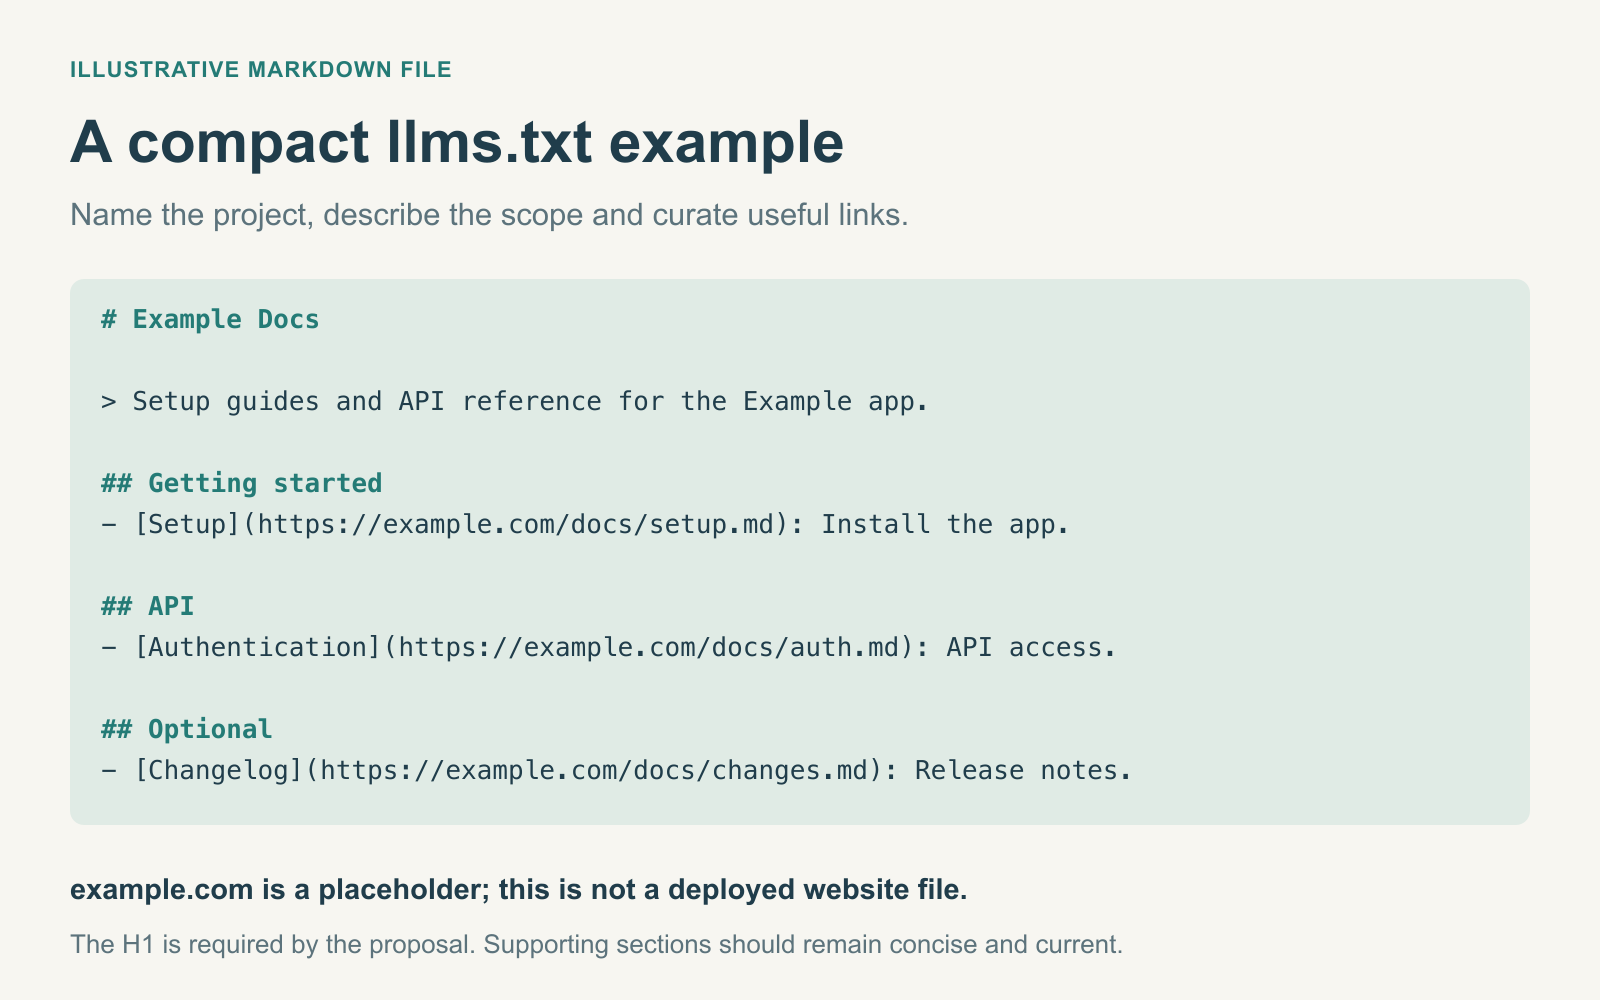
The August 2026 proposal requires an H1 containing the site or project name. It also supports a summary, explanatory text, and H2 sections containing lists of links.
Here’s an illustrative example for DigitalMarketingTools.ai, using existing published pages:
# DigitalMarketingTools.ai

> Independent guides and comparisons covering
> digital marketing software, SEO, and GEO.

## Generative Engine Optimization

- [GEO Tools Guide](https://digitalmarketingtools.ai/geo/geo-tools-guide/): Overview of GEO tools, AI visibility, and evaluation criteria.
- [AI Citation Tracking](https://digitalmarketingtools.ai/geo/what-is-an-ai-citation-tracking-tool/): Explains how AI citations are identified and measured.

## Editorial Standards

- [How We Review GEO Tools](https://digitalmarketingtools.ai/geo/how-we-review-geo-tools/): Evaluation criteria, limitations, and evidence standards.
This is an illustrative file structure using verified public pages, not a claim that it is the website’s currently deployed llms.txt file.
Notice that the descriptions explain what each resource provides.
They don’t make unsupported assertions about the pages being preferred by AI systems.
For a root-level implementation, upload the file so that it is accessible at /llms.txt.
The current proposal also permits files at more specific paths, allowing a documentation section to maintain its own guide.
Check that the server returns a successful response and the expected content. Confirm that all links resolve to their intended destinations.
A correctly formatted document isn’t useful if half its references are broken or outdated.
The revised proposal encourages making LLM-friendly Markdown representations available and identifying them through appropriate link relations.
This can be useful for documentation websites with complex HTML layouts.
However, generating an alternative version of every content page creates more work and potential inconsistencies.
If the HTML page and Markdown version contain conflicting information, an agent may retrieve the wrong version.
For most small marketing websites, maintaining separate Markdown copies of every article is difficult to justify without a specific consumer that benefits from them.
An llms.txt file should be updated when important linked pages move, product information changes, or new resources replace outdated material.
For documentation-heavy websites, automated generation may be preferable to manually maintaining a second content index.
For smaller websites, a periodic review alongside technical SEO maintenance may be sufficient.
The objective is to prevent the file from becoming another outdated asset that nobody owns.
Several publishing platforms and SEO products now support generating llms.txt files.
The proposal’s own documentation references integrations with platforms such as Mintlify, GitBook, Yoast SEO, Wix, and other content management or documentation tools.
These integrations can reduce manual work, particularly when the file can be refreshed as the underlying website changes.
However, a generator should be assessed according to the quality and maintenance of its output, not promises of improved AI rankings.
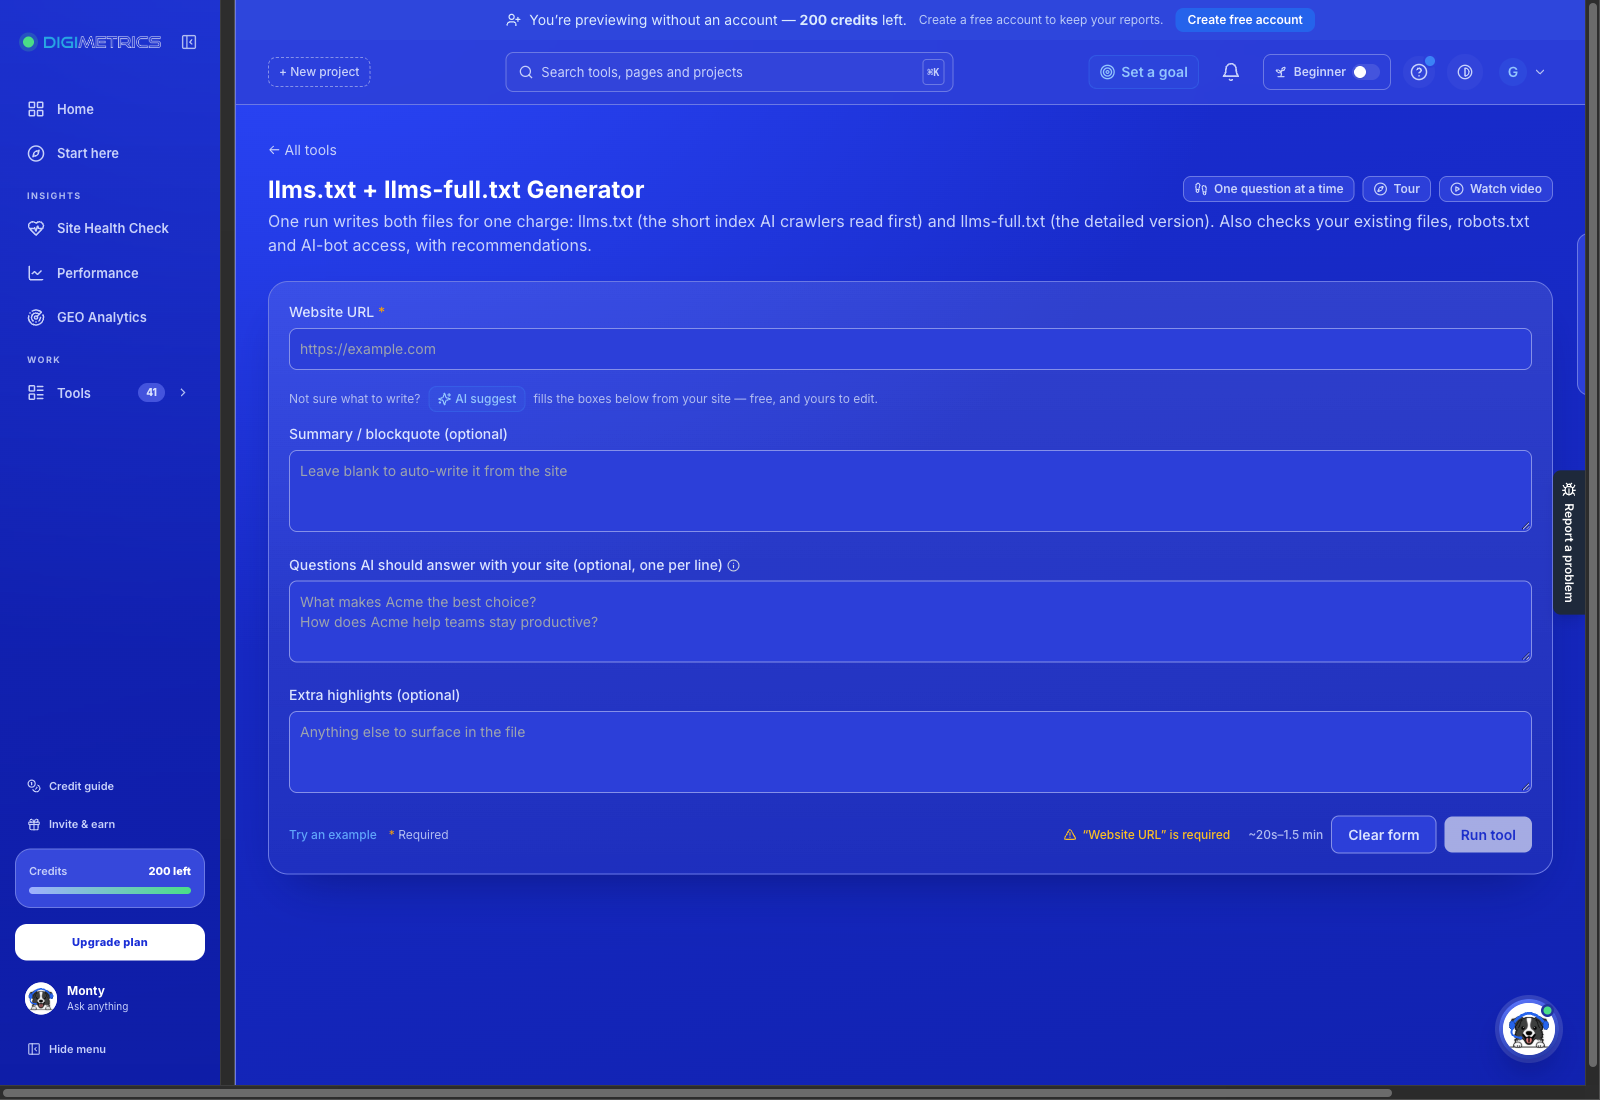
Best suited for: Marketers and agencies that want to generate an llms.txt file and review related technical readiness within a broader SEO and GEO workflow.
Digimetrics.ai offers an llms.txt and llms-full.txt generator.
According to its product documentation, the tool can examine whether a website already has an llms.txt file, check AI-related crawler access, identify important pages, and generate both a concise index and a longer reference document.
This may reduce implementation work for teams that don’t want to assemble the files manually.
The platform also provides an AI Readiness Check and broader technical and AI visibility tools, allowing the file-generation task to sit alongside other website diagnostics.
However, these are documented capabilities, not evidence that the generated files increase ChatGPT citations or Google AI visibility.
Our assessment: Digimetrics is worth evaluating when the practical challenge is preparing and maintaining an llms.txt file alongside other SEO work. Its generator should be judged on page selection, factual accuracy, valid links, and editing time—not on an assumed ranking benefit.
Whether the tool is free, bundled with an SEO plugin, or included in a paid platform, I’d assess four things:
| Criterion | What to Verify |
|---|---|
| Page selection | Does it prioritize genuinely important and current resources? |
| Factual accuracy | Are descriptions consistent with the linked pages? |
| Maintenance | Can the file be updated without rebuilding everything manually? |
| Editing effort | How much time is required to review and correct the output? |
If a generator includes outdated pages, invents descriptions, or introduces broken URLs, its automation may create more problems than it solves.
This is where most implementation advice becomes less convincing.
Creating a file is easy to verify.
Demonstrating that it improves AI discovery or answer quality is much harder.
For AI search monitoring, the problem is that generated answers can change between requests, even when a website hasn’t changed.
Differences in prompts, models, retrieval sources, locations, and dates can all affect which pages appear.
Our guide to measuring GEO performance explains why AI visibility metrics need clearly defined sources and collection methods.
A useful llms.txt evaluation should therefore distinguish technical correctness, actual consumption, and downstream outcomes.
Before publishing the file, document the website’s existing technical condition.
Record whether important pages are accessible, whether relevant bots encounter restrictions, and whether there are known indexing or server-response problems.
If you are also tracking AI visibility, preserve the exact prompts, platforms, response dates, and citation URLs used for the baseline.
Without that information, later comparisons become difficult to interpret.
Once the file is live, confirm that it returns the intended content and that linked resources are accessible.
You can use server logs to investigate whether requests for /llms.txt occur.
But the user-agent string alone isn’t reliable proof of the requester’s identity. Where possible, verify requests using the provider’s documented bot verification methods and published IP information.
Also distinguish requests to the llms.txt file from requests to the pages it lists.
A successful fetch proves that a client obtained the resource. It does not prove that the resource affected an AI-generated answer.
A controlled task is more informative than simply waiting for AI citations to change.
For example, if your website provides API documentation, configure a compatible agent to answer a fixed set of technical questions.
Run the tasks under comparable conditions, with and without access to the curated guide.
Measure whether the agent identifies the correct documentation pages, provides accurate answers, and completes the tasks successfully.
If the experiment controls the agent and the retrieval process, you can obtain evidence about that specific workflow.
However, demonstrating that an agent performs better when explicitly supplied with llms.txt is not the same as showing that ChatGPT Search independently discovers and uses the file.
If you’re interested in broader AI search visibility, track relevant brand mentions, source citations, and referral traffic.
For a manageable pilot, maintain a fixed set of approximately 20 relevant questions and collect repeated observations across a baseline and follow-up period.
Record the AI platform, prompt, date, brand mentions, cited URLs, and response changes.
Keep the measurement conditions as consistent as practical.
For a deeper explanation of the difference between being mentioned and being cited, see our AI citation tracking guide.
If citations increase after implementation, record the observation without immediately attributing the change to llms.txt.
Unless you can establish that the system used the file and that the change resulted from that use, the causal claim remains unproven.
At the end of the pilot, ask:
A useful implementation should have a defined consumer or demonstrable operational value.
Otherwise, it may be better categorized as optional infrastructure rather than a successful optimization.
The file itself doesn’t need to be expensive.
But the cost is not limited to generating it.
Someone may need to select resources, verify descriptions, review links, publish the file, inspect logs, and update it after important website changes.
For a small website, these tasks may take little time. For a large website with frequently changing documentation, the maintenance effort can become substantial.
Assume a company uses an existing tool that requires no additional subscription.
It spends two hours preparing and reviewing its initial file, followed by 30 minutes each month for maintenance.
At an internal labor cost of $50 per hour:
| Cost Component | Illustrative Cost |
|---|---|
| Initial preparation: 2 hours | $100 |
| Six monthly reviews: 3 hours total | $150 |
| Additional software cost | $0 |
| Total six-month cost | $250 |
These figures are hypothetical.
The $250 cost might be entirely reasonable if the file helps a documented agent workflow answer frequently requested technical questions.
It is harder to justify as a marketing investment if the only observed result is that the file exists.
The more useful question is not necessarily cost per generated file, but cost per verified improvement in a relevant task.
A team shouldn’t manufacture a favorable return on investment by counting the number of links added or declaring each generator warning resolved to be a business benefit.
These files aren’t direct alternatives.
If the objective is managing crawler access, robots.txt remains the relevant mechanism for compliant crawlers.
If the objective is helping supported search engines discover website URLs, XML sitemaps and established SEO practices remain important.
If the objective is giving compatible AI agents a curated navigation guide, llms.txt may be useful.
You can implement all three, but each should have a defined role.
For ChatGPT Search specifically, OpenAI’s crawler documentation provides direct guidance on OAI-SearchBot access. That is a more established starting point for investigating search discovery than assuming a newly published llms.txt file will influence inclusion.
Similarly, Google recommends existing SEO fundamentals, useful content, technical accessibility, and Search Console reporting rather than special AI text files.
The presence of an llms.txt file doesn’t override blocked resources, fix broken pages, or make an otherwise unsuitable page eligible for AI search.
Rather than treating the file as mandatory, I’d base the decision on the website’s use case.
| Website or Situation | Recommendation | Reason |
|---|---|---|
| API documentation or developer portal | Worth testing | Compatible agents may benefit from curated documentation paths |
| Organization building its own AI agent | Worth testing | The consuming system can explicitly use and evaluate the file |
| Large reference website | Consider a pilot | Could simplify access to important resources |
| Small business website | Low priority | Existing accessible pages may already answer the relevant questions |
| Publisher seeking higher Google AI rankings | Not a priority for that objective | Google Search explicitly ignores the file |
| Website with major technical SEO problems | Fix existing issues first | A curated guide won’t resolve underlying accessibility or content problems |
| Website with automatic, maintainable generation | Reasonable optional addition | Lower incremental cost, provided the output is accurate |
The recommendation changes if a specific platform officially documents support or your own testing demonstrates value.
Until then, the prudent approach is to treat llms.txt as a selective technical experiment rather than a universal requirement.
If your goal is improving visibility in AI-generated answers, several activities have more direct evidence or clearer diagnostic value.
Check whether relevant search and retrieval systems can access the pages you want discovered.
Investigate robots rules, server responses, redirects, and content that requires unnecessary client-side processing.
This doesn’t guarantee citations, but it helps avoid technical barriers to retrieval.
Original research, accurate product documentation, well-supported comparisons, and useful explanations give both human readers and AI systems substantive information to work with.
A generic article rewritten to be more AI-friendly is not necessarily more useful than an established page containing original data or detailed expertise.
Clear headings, appropriate internal links, logical navigation, and descriptive page titles help users and automated systems find relevant information.
Those improvements can benefit the website beyond any single AI platform.
Brand mentions, source citations, first-party search impressions, and referral traffic measure different outcomes.
A tool that reports an overall AI visibility score without explaining its underlying observations may create more uncertainty than it removes.
Our GEO tool review methodology explains how to evaluate these measurements without inventing precision.
These established tasks should form the foundation of an AI search strategy. An llms.txt file can then be assessed as an additional, limited-purpose tool.
This assessment draws on the current llms.txt proposal, official Google Search guidance, Chrome Lighthouse documentation, AI provider crawler information, and publicly documented software capabilities.
We separate three categories of evidence:
| Evidence Category | Interpretation |
|---|---|
| Documented platform behavior | A provider explicitly states how its systems handle the file |
| Demonstrated implementation | A website, generator, or agent can publish or consume the format |
| Measured outcome | A reproducible test demonstrates a defined benefit under specified conditions |
These categories should not be treated as interchangeable.
The proposal has attracted meaningful implementation support, particularly in documentation and agent-related workflows.
However, we have not identified sufficient independently verified evidence to assign a general AI citation uplift, ranking benefit, or return on investment to publishing llms.txt.
The testing approach described in this article is a proposed evaluation methodology, not a completed controlled experiment.
Any future benchmark should publish its test environment, file contents, collection methods, agent configurations, task results, and limitations.
The argument for llms.txt is easy to understand.
AI agents frequently need to navigate websites and locate useful information. A concise, structured guide could help them do that without processing unnecessary content.
The August 2026 update made the proposal more practical, particularly for documentation websites and agent-based workflows.
But the case for improved AI search visibility remains substantially weaker.
Google explicitly states that Search ignores the file. Other major AI platforms have not established universal automatic consumption as a ranking or recommendation mechanism. And publishing the file doesn’t demonstrate that any resulting change in brand mentions or citations was caused by its presence.
For developer documentation, complex reference websites, and organizations building their own agents, llms.txt deserves a controlled test.
For most ordinary marketing websites, it belongs behind accessible content, sound technical SEO, accurate information, and reliable measurement.
If generation is automated and maintenance is inexpensive, publishing the file can be a reasonable optional addition.
Just don’t confuse ease of implementation with evidence of effectiveness.
The question isn’t whether an AI-friendly website guide is a good idea. It’s whether the AI systems relevant to your business actually use that guide—and whether its use produces a benefit you can demonstrate.
Until that evidence exists, llms.txt should be treated as an experiment worth evaluating, not a requirement every business must rush to satisfy.
For further research on AI visibility, technical readiness, and measurement tools, explore our GEO articles and guides.
llms.txt is a proposed Markdown-based convention that gives compatible AI agents a concise guide to a website’s important information. It can list documentation, reference pages, policies, and other resources. Its primary proposed purpose is helping agents locate useful content, not controlling crawler access or guaranteeing AI search visibility.
There is no sufficient public evidence that publishing llms.txt generally improves search rankings. Google explicitly states that its Search systems, including generative AI Search features, do not use these files as an optimization signal.
Google Search doesn’t use llms.txt for rankings or visibility in its AI search features. Chrome Lighthouse separately recognizes it as an optional convention for agentic browsing audits. These serve different purposes and should not be confused.
OpenAI publishes an llms.txt file for its developer documentation, but this does not establish that ChatGPT Search automatically retrieves or prioritizes every website’s file. OpenAI’s official crawler guidance focuses on search crawler access rather than promising llms.txt-based visibility.
No. Generative Engine Optimization includes content quality, technical accessibility, AI visibility measurement, and other activities. llms.txt is an optional proposal, not a requirement for appearing in AI-generated answers.
llms.txt is a concise, structured guide to a website’s important resources. llms-full.txt is a longer companion document that may contain expanded information for compatible tools. Neither file guarantees that an external AI search engine will use it.
No. robots.txt communicates crawler access restrictions and preferences to compliant bots. llms.txt provides an informational guide to website content. Publishing one doesn’t replace the purpose of the other.
Yes. The file can be written manually as Markdown and uploaded to a website. Some content management systems and documentation platforms can also generate it automatically. Digimetrics provides an llms.txt generator as part of its marketing toolkit.
Not necessarily. Websites with complex documentation or known agent workflows may benefit from testing it. For smaller websites with straightforward content, other improvements may offer more immediate value. A universal implementation requirement isn’t supported by current evidence.
Server logs may show requests to the file, although bot identities should be verified where possible. A request establishes that a client accessed the resource, not that it influenced an answer. A more meaningful test examines whether a defined agent workflow performs better with the file than without it.
Review the file whenever important linked resources change, especially when documentation, product information, or site structure is updated. Automated generation can reduce maintenance, but generated descriptions and destinations still require quality checks.
It can be worthwhile as a low-cost, maintained resource for compatible agents or documentation workflows. It is not currently justified as a guaranteed AI search ranking or citation technique. Prioritize it according to a specific use case and measurable benefit.

Tom is the CEO of MediaOne, a leading digital marketing agency. He is a business-experienced SEO consultant as well as a Google Gold Search Expert serving the international community. He has consulted for MNCs like Canon, Maybank, Capitaland, SingTel, ST Engineering, WWF, Cambridge University, as well as Government organisations like Enterprise Singapore, Ministry of Law, National Galleries, NTUC, e2i, SingHealth. His articles are published and referenced in CNA, Straits Times, MoneyFM, Financial Times, Yahoo! Finance, Hubspot, Zendesk, CIO Advisor. Under his stewardship, MediaOne has won dozens of prestigious digital marketing awards.
Run a free Digimetrics audit across SEO, AI search, content and technical health, and get a plan you can act on today.
Start free →Yes, Ahrefs has a free AI Visibility Checker. You can enter a brand name, inspect its presence across six AI search experiences, and see…
Your website ranks on Google. Your SEO dashboard shows healthy organic traffic, and your brand appears for several commercially valuable keywords. But when someone…
Direct answer: To rank in Perplexity and ChatGPT, answer one narrow question clearly, make each claim easy to check, and structure the page so…